TOPIC: PHP
A reasonable requirement of an IDE
 20th May 2008
I have been having a play with NetBeans IDE Early Access for PHP and, while it has a lot to offer, one impression remains uppermost in my mind: it is so slow. While I might have a project with many files in it, start-up takes an age because of project checking. Other functionality such as text searching is far from speedy either. The sluggishness probably arises from this release being very early in its life cycle, and it reminds me of how slow older versions of the Java IDE were, even if this is slower. For PHP development, I'll be giving NetBeans a while to mature before taking another look at it.
On a similar note, I recently dispatched Quanta Plus from my system for sluggish start-ups and will not return to it because other alternatives such as Bluefish and Eclipse PDT fit my needs much better. I like my editors to be slick and responsive, and Quanta has been around long enough for any slowness to be knocked out of it. However, I get the feeling that the extras have added bloat, while I expect any additional functionality that I never use not to get in my way. It is for the latter reason that I was always able to get on with Dreamweaver and even run it on Ubuntu using the WINE library. If I really wanted a stripped out yet functional editor, Gedit would do most of what I need - it colour-codes syntax for a variety of languages for a start - but it's always handy to have a file system explorer window incorporated and I value any syntax checking and auto-completion as well. So, it looks as if Eclipse and Bluefish could be serving my needs for a while to come, alongside so use Dreamweaver for online editing of website files.
A collection of lessons learnt about web hosting
28th March 2008
Putting this blog back on its feet after a spot of web hosting bother caused me to learn a bit more about web hosting than I otherwise might have done. Here's a selection, and they are in no particular order:
- Store your passwords securely and where you can find them because you never know how a foul up of your own making can strike. For example, a faux pas with a configuration file is all that's needed to cause havoc for a database site such as a WordPress blog. After all, nobody's perfect and your hosting provider may not get you out of trouble as quickly as you might like.
- Get a MySQL database or equivalent as part of your package, rather than buying one separately. If your provider allows a trial period, then changing from one package to another could be cheaper and easier than if you bought a separate database and needed to jettison it because you changed from, say, a Windows package to a Linux one or vice versa.
- It might be an idea to avoid a reseller unless the service being offered is something special. Going for the sake of lower cost can be a false economy, and it might be better to cut out the middleman altogether and go direct to their provider. Being able to distinguish a reseller from a real web host would be nice, but I don't see that ever becoming a reality; it is hardly in the resellers' interests, after all.
- Should you stick with a provider that takes several days to resolve a serious outage? The previous host of this blog had a major MySQL server outage that lasted for up to three days, and seeing that was one of the factors that made me turn tail to go to a more trusted provider that I have used for a number of years. The smoothness of the account creation process might be another point worthy of consideration.
- Sluggish system support really can frustrate, especially if there is no telephone support provided and the online ticketing system seems to take forever to deliver solutions. I would advise strongly that a host who offers a helpline is a much better option than someone who doesn't. Saying all of that, I think that it's best to be patient and, when your website is offline, that might not be as easy you'd hope it to be.
- Setting up hosting or changing from one provider to another can take a number of days because of all that needs doing. So, it's best to allow for this and plan ahead. Account creation can be quick but setting up the website can take time while domain name transfer can take up to 24 hours.
- It might not take the same amount of time to set up Windows hosting as its Linux equivalent. I don't know if my experience was typical, but I have found that the same provider set up Linux hosting far quicker (within 30 minutes) than it did for a Windows-based package (several hours).
- Be careful what package you select; it can be easy to pick the wrong one, depending on how your host's sight is laid out and what they are promoting at the time.
- You can have a Perl/PHP/MySQL site working on Windows, even with IIS being used in place instead of Apache. The Linux/Apache/Perl/PHP/MySQL approach might still be better, though.
- The Windows option allows for .Net, ASP and other such Microsoft technologies to be used. I have to say that my experience and preference is for open-source technologies, so Linux is my mainstay, but learning about the other side can never hurt from a career point of view. After, I am writing this on a Windows Vista powered laptop to see how the other half lives, as much as anything else.
- Domains serviced by hosting resellers can be visible to the systems of those from whom they buy their wholesale hosting. This frustrated my initial attempts to move this blog over because I couldn't get an account set up for technologytales.com because a reseller had it already on the same system. It was only when I got the reseller to delete the account with them that things began to run more smoothly.
- If things are not going as you would like them, getting your account deleted might be easier than you think, so don't procrastinate because you think it is a hard thing to do. Of course, it goes without saying that you should back things up beforehand.
java.net.MalformedURLException: unknown protocol: j
15th December 2007
While I know that there are better things to call a blog post than to use part of an error message that I got from Saxonica's Saxon when I was converting XML files into PHP equivalents for the visitor information section of my main website, it is handy for anyone else needing to look up a solution when they encounter it. In my case, I use the open source Saxon-B rather than the commercial Saxon-SA, and it fulfils all of my needs. Version 8 and later (it has now reached 9.0.0.2) handle the XSLT 2.0 features that I need to make the transformations really clever.
Also, because Saxon is available as a jar file, it is cross-platform so long as you have Java on board. There are, however, some slight differences in behaviour. Now, I run the thing on Linux, where any Windows-style file locations are not recognised. When I had the file path in a DTD declaration starting with J:\, that was thought to be a protocol like file, http, https, ftp and so on because of the colon. Since there's no j protocol, Java gets confused, issuing the rather obscure error that titles this post. Otherwise, the migration of the Perl script that creates XSLT files and fires off the required XML to PHP transformations was a fairly straightforward exercise once file locations and shebang line were set right.
Setting up a test web server on Ubuntu
1st November 2007
Installing all the bits and pieces is painless enough so long as you know what's what; Synaptic does make it thus. Interestingly, Ubuntu's default installation is a lightweight affair with the addition of any additional components involving downloading the packages from the web. The whole process is all very well integrated and doesn't make you sweat every time you need to install additional software. In fact, it resolves any dependencies for you so that those packages can be put in place too; it lists them, you select them and Synaptic does the rest.
Returning to the job in hand, my shopping list included Apache, Perl, PHP and MySQL, the usual suspects in other words. Perl was already there, as it is on many UNIX systems, so installing the appropriate Apache module was all that was needed. PHP needed the base installation as well as the additional Apache module. MySQL needed the full treatment too, though its being split up into different pieces confounded things a little for my tired mind. Then, there were the MySQL modules for PHP to be set in place too.
The addition of Apache preceded all of these, but I have left it until now to describe its configuration, something that took longer than for the others; the installation itself was as easy as it was for the others. However, what surprised me were the differences in its configuration set up when compared with Windows. There are times when we get the same software but on different operating systems, which means that configuration files get set up differently. The first difference is that the main configuration file is called apache2.conf on Ubuntu rather than httpd.conf as on Windows. Like its Windows counterpart, Ubuntu's Apache does use subsidiary configuration files. However, there is an additional layer of configurability added courtesy of a standard feature of UNIX operating systems: symbolic links. Rather than having a single folder with the all configuration files stored therein, there are two pairs of folders, one pair for module configuration and another for site settings: mods-available/mods-enabled and sites-available/sites-enabled, respectively. In each pair, there is a folder with all the files and another containing symbolic links. It is the presence of a symbolic link for a given configuration file in the latter that activates it. I learned all this when trying to get mod_rewrite going and changing the web server folder from the default to somewhere less susceptible to wrecking during a re-installation or, heaven forbid, a destructive system crash. It's unusual, but it does work, even if it takes that little bit longer to get things sorted out when you first meet up with it.
Apart from the Apache set up and finding the right things to install, getting a test web server up and running was a fairly uneventful process. All's working well now, and I'll be taking things forward from here; making website Perl scripts compatible with their new world will be one of the next things that need to be done.
On Blogrolling.com
6th October 2007
I was ambling around the web and came across a website that, while it appeared to be a blog, isn't one in the vein of that to which we are accustomed. It does, however, have a blogroll and that is where Blogrolling.com comes into this piece. Blogrolls are very much a feature of the blogging (WordPress calls them that anyway) world and act as a repository of useful links relevant to the subject of the blog. I also use them as a bookmarking station for myself and a way to return the favour when someone links to my blog. For a blogroll, you generally need a database sitting behind in the background, or you end up creating a list of links in (X)HTML.
Blogrolling.com offers another option: placing your links at an external website and including them on your webpages, using a piece of code to pull in the information. RSS, JavaScript and PHP are among the methods on offer from Blogrolling.com; I used PHP when I gave the service a whirl on one of my offline blogs and that really does give you a lot of customising power over and above using CSS. That's not to say that there aren't customisation functions on offer from Blogrolling.com, I found a few of these distinctly useful: ordering of links in a blogroll is just one. When it comes to categorising your links, you don't get the category option, but you do get to create as many blogrolls as you want, so there is a workaround; moving links from one blogroll to another is mouse intensive but straightforward. Also, because you are reading each blogroll in turn, you can order the categories as you want them. With WordPress' category approach, ordering categories involves widgets and plugins or getting your hands dirty with some code cutting. All in all, Blogrolling.com seems to offer an intriguing and useful service.
The wonders of mod_rewrite
24th June 2007
When I wrote about tidying dynamic URL's a little while back, I had no inkling that that would be a second part to the tale. My discovery of mod_rewrite, an Apache module that facilitates URL translation. The effect is that one URL is presented to the user in the browser address bar, and the very same URL is also seen by search engines, while another is passed to the server for processing. Though it might sound like subterfuge, it works very well once you manage to get it set up properly. While the web host for my hillwalking blog/photo gallery has everything configured such that it is ready to go, the same did not apply to the offline Apache 2.2.x server that I have going on my own Windows XP box. There were two parts to getting it working there:
- Activating mod-rewrite on the server: this is as easy as uncommenting a line in the
httpd.conffile for the site (the line in question is:LoadModule rewrite_module modules/mod_rewrite.so). - Ensuring that the
.htaccessfile in the root of the web server directory is active. You need to set the values of theAllowOverridedirectives for the server root and CGI directories toAllso that.htaccessis active. Not doing it for the latter will result in an error beginning with the following:Options FollowSymLinks or SymLinksIfOwnerMatch is off which implies that. HavingRewriteRuledirective is forbiddenAllow from Allset for the required directories is another option to consider when you see errors like that.
Once you have got the above sorted, add this line to .htaccess: RewriteEngine On. Preceding it with an Options directive to ensure that FollowSymLinks and SymLinksIfOwnerMatch are switched on does no harm at all and may even be needed to get things running. That done, you can set about putting mod_write to work with lines like this:
RewriteRule ^pages/(.*)/?$ pages.php?query=$1
The effect of this is to take http://www.website.com/pages/input and convert it into a form for action by the server; in this case, that is http://www.website.com/pages.php?query=input. Anything contained by a bracket is assigned to the value of a system-named variable. If you have several bracketed sections, they are assigned to sequentially numbered variables as follows: $1 for the first, $2 for the second and so on. It's all good stuff when you get it going, and not only does it make things look much neater, but it also possesses an advantage when it comes to future-proofing too. Web addresses can be kept constant over time, even if things change behind the scenes. It means that any returning visitors will find what they saw the last time that they visited and surely must ensure good karma in the eyes of those all important search engines.
Tidying dynamic URL’s
15th June 2007
A few years back, I came across a very nice article discussing how you would make a dynamic URL more palatable to a search engine, and I made good use of its content for my online photo gallery. The premise was that URL's that look like that below are no help to search engines indexing a website. Though this is received wisdom in some quarters, it doesn't seem to have done much to stall the rise of WordPress as a blogging platform.
http://www.mywebsite.com/serversidescript.php?id=394
That said, WordPress does offer a friendlier URL display option too, which you can see in use on this blog; they look a little like the example URL that you see below, and the approach is equally valid for both Perl and PHP. Since I have been using the same approach for the Perl scripts powering my online phone gallery, now want to apply the same thinking to a gallery written in PHP:
http://www.mywebsite.com/serversidescript.pl/id/394
The way that both expressions work is that a web server will chop pieces from a URL until it reaches a physical file. For a query URL, the extra information after the question mark is retained in its QUERY_STRING variable, while extraneous directory path information is passed in the variable PATH_INFO. For both Perl and PHP, these are extracted from the entries in an array; for Perl, this array is called is $ENV and $_SERVER is the PHP equivalent. Thus, $ENV{QUERY_STRING} and $_SERVER{'QUERY_STRING'} traps what comes after the ? while $ENV{PATH_INFO} and $_SERVER{'PATH_INFO'} picks up the extra information following the file name (/id/394/ in the example). From there on, the usual rules apply regarding cleaning of any input but changing from one to another should be too arduous.
Perl vs. PHP: A Personal Experience
11th June 2007
Ever since I converted it from a client-side JavaScript-powered affair, my online photo gallery has been written in Perl. There have been some challenges along the way, figuring out how to use hash tables has been one, but everything has worked as expected. However, I am now wondering if it is better to write things in PHP for the sake of consistency with the rest of the website. I had a go a rewriting the random photo page and, unless I have been missing something in the Perl world, things do seem more succinct with PHP. For instance, actions that formerly involved several lines of code can now be achieved in one. Reading the contents of a file into an array and stripping HTML/XML tags from a string fall into this category, and seeing the number of lines of code halving is a striking observation. I am not going to completely abandon Perl, it's a very nice language, but I do rather suspect that there is now an increased chance of my having a website whose server-side processing needs are served entirely by PHP.
Getting one’s HTTP headers in a twist
9th June 2007
I am in the process of further linking the content of hillwalking blog into the fabric of other parts of my website. To date, this has included adding a list of all the posts to the site map and a dossier of the latest entries to the site's welcome page. One thing that started to crop up were a series of warnings of the form:
Cannot modify header information - headers already sent by...
The cause of this was my calling a PHP script that was part of my hillwalking blog installation, and this caused Bad Behaviour to be invoked. The result was that an HTTP header was being sent to create a cookie after one already had been sent to display a web page. A spot of conditional coding and the use of an extra flag resolved the problem.
Apparently, there is another surefire way of getting the same result: whitespace before or after the <?php ... ?> tag in an included script. The cookie issue is one that I can understand, but it does seem strange that an attempt is made to send HTTP header information when the latter arises. It causes loads of questions, though...
SQL Developer Java error
6th June 2007
Last night, I tried starting up Oracle's SQL Developer so that I could add a listing of my hillwalking blog posts to my website's site map with a spot of PHP scripting. However, all that I got was something like that which you see below:
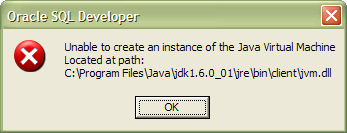
I must confess that this one threw me. The solution, though challenging to find (they often are, even with the abilities of Google) was to use a batch file called sqldeveloper.bat that you can find in the [installation directory]\sqldeveloper\bin directory. It does start the thing when all else seems to fail and got me up and running again. I did get that blog post listing added to the site map after all; Having more visibility of the MySQL tables was a definite plus point.